BRICS AI Economics

Tag: LLM quantization

post-image
Oct, 5 2025

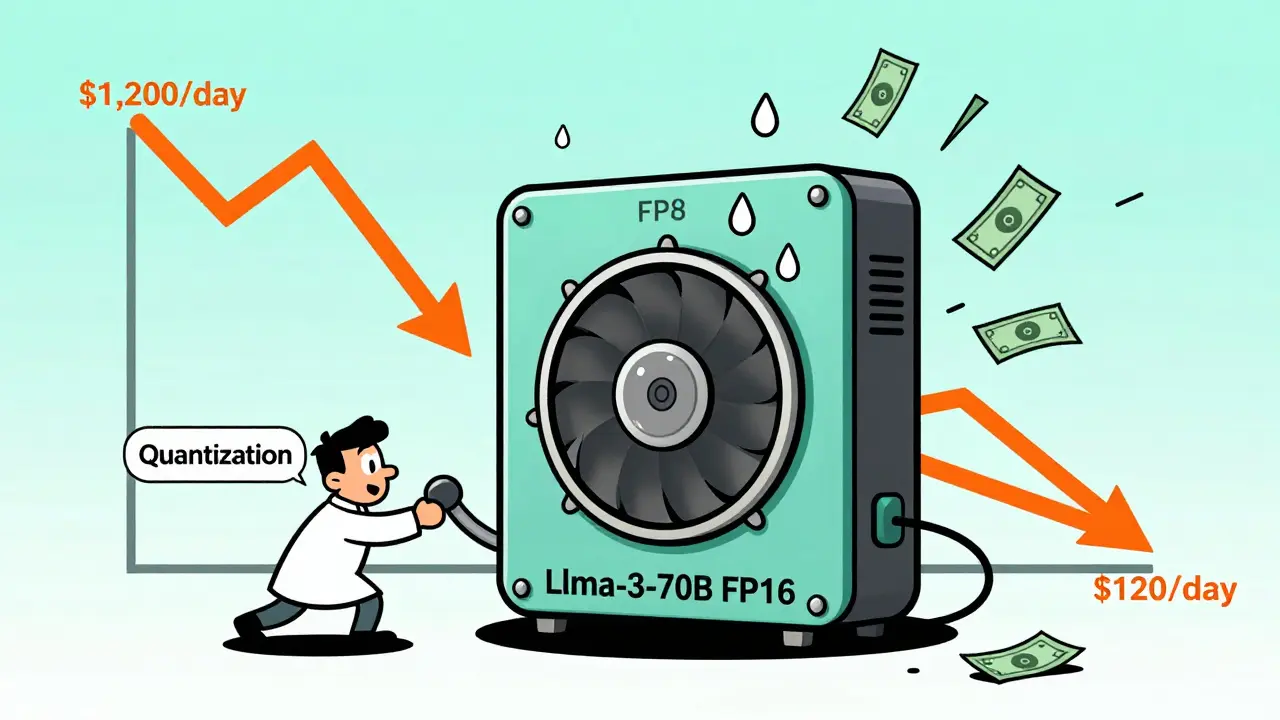
Cost-Performance Tuning for Open-Source LLM Inference: How to Slash Costs Without Losing Quality

Emily Fies
10
Learn how to cut LLM inference costs by 70-90% using open-source tools like vLLM, quantization, and Multi-LoRA-without sacrificing performance. Real-world strategies for startups and enterprises.
Categories

  • AI Engineering (127)
  • Business (68)
  • Strategy & Governance (21)
  • Security (19)
  • Biography (7)

Latest Courses

  • post-image

    Hardware Acceleration for Multimodal Generative AI: GPUs, NPUs, and Edge

  • post-image

    Generative AI for Finance: Automating Forecasts and Variance Narratives

  • post-image

    Vibe Coding Ethics: Who Owns the Bug?

  • post-image

    Mastering Style Transfer Prompts in Generative AI: Tone, Voice, and Format

  • post-image

    Vibe Coding Customer Portals: Authentication, Profiles & Notifications

Popular Tags

  • vibe coding
  • large language models
  • prompt engineering
  • generative AI
  • AI coding assistants
  • vLLM
  • attention mechanism
  • rapid prototyping
  • LLM fine-tuning
  • multimodal AI
  • LLMs
  • data privacy
  • LoRA
  • Generative AI
  • AI governance
  • LangChain
  • RAG
  • AI coding
  • Large Language Models
  • GDPR compliance
BRICS AI Economics

© 2026. All rights reserved.