Traditional model validation is dead. If you are still treating Large Language Models (LLMs) like standard supervised learning algorithms-checking them once a quarter and calling it good-you are flying blind. The shift from deterministic code to probabilistic generation has broken the old rules of Risk Management. LLMs are stochastic, opaque "black boxes" that produce different outputs every time you ask the same question. This nondeterminism, combined with the rise of agentic systems that can take autonomous actions, demands a completely new approach to governance. You need dynamic controls, real-time observability, and clear escalation paths that trigger before a minor hallucination becomes a major compliance breach.
Why Traditional MRM Fails for Generative AI
Model Risk Management (MRM) frameworks were built for a world where inputs led to predictable outputs. A credit scoring model either approved a loan or didn’t. An LLM, however, might approve a loan with a rationale that changes subtly between runs. This variability invalidates static testing cycles. When an LLM acts as an agent-using tools, reading files, and making decisions-the risk surface expands exponentially. You aren't just managing the output text; you are managing the chain of reasoning and the external actions taken based on that reasoning.
The core problem is interpretability. In traditional ML, you could often trace why a decision was made. With LLMs, the internal structure is dense and high-dimensional. We rely on proxy metrics and behavioral testing instead of structural inspection. This means your risk controls must focus less on how the model thinks and more on what it does. If an agent decides to delete a database table because it misinterpreted a prompt, the internal logic matters less than the immediate ability to stop the action.
The Five Dimensions of LLM Risk Assessment
To build effective controls, you first need to categorize the risks. Standard enterprise risk categories don't fully capture the nuances of generative AI. Instead, security researchers and governance experts use five specific dimensions to assess threat levels:
- Damage Potential: How much harm can this specific LLM application cause? A chatbot suggesting movie recommendations has low damage potential. An agent executing SQL queries on production data has high damage potential.
- Reproducibility: Can an adversary reliably replicate a vulnerability? If a jailbreak works consistently, it’s easier to patch. If it’s random, it’s harder to test against.
- Exploitability: How easy is it for a bad actor to access and manipulate the model? Public-facing APIs are highly exploitable compared to internal, air-gapped models.
- Affected Users: What is the blast radius? Does a failure affect one user’s workflow or corrupt data for thousands of downstream consumers?
- Discoverability: How visible are the vulnerabilities? Some risks are obvious (e.g., PII leakage in logs), while others are subtle (e.g., slight bias in hiring recommendations).
By scoring each LLM deployment against these dimensions, you can assign appropriate control tiers. High-damage, high-exploitability systems need rigorous, real-time monitoring. Low-risk internal tools can get by with periodic audits.
Technical Controls That Actually Work
You cannot govern what you do not observe. Effective LLM risk management relies on a layered defense strategy involving both architectural choices and runtime controls. Here are the most effective technical measures currently available:
| Control Mechanism | Primary Function | Best Use Case |
|---|---|---|
| Data Minimization | Reduces attack surface by limiting context window data. | PII protection and cost reduction. |
| Adversarial Training | Hardens model against known jailbreaks and edge cases. | Public-facing chatbots and agents. |
| Federated Learning | Distributes training data to prevent central point of failure. | Multi-entity collaborations with strict privacy needs. |
| Differential Privacy | Adds statistical noise to protect individual data points. | Healthcare and financial data processing. |
| RLHF | Aligns outputs with human values via feedback loops. | Reducing toxicity and improving helpfulness. |
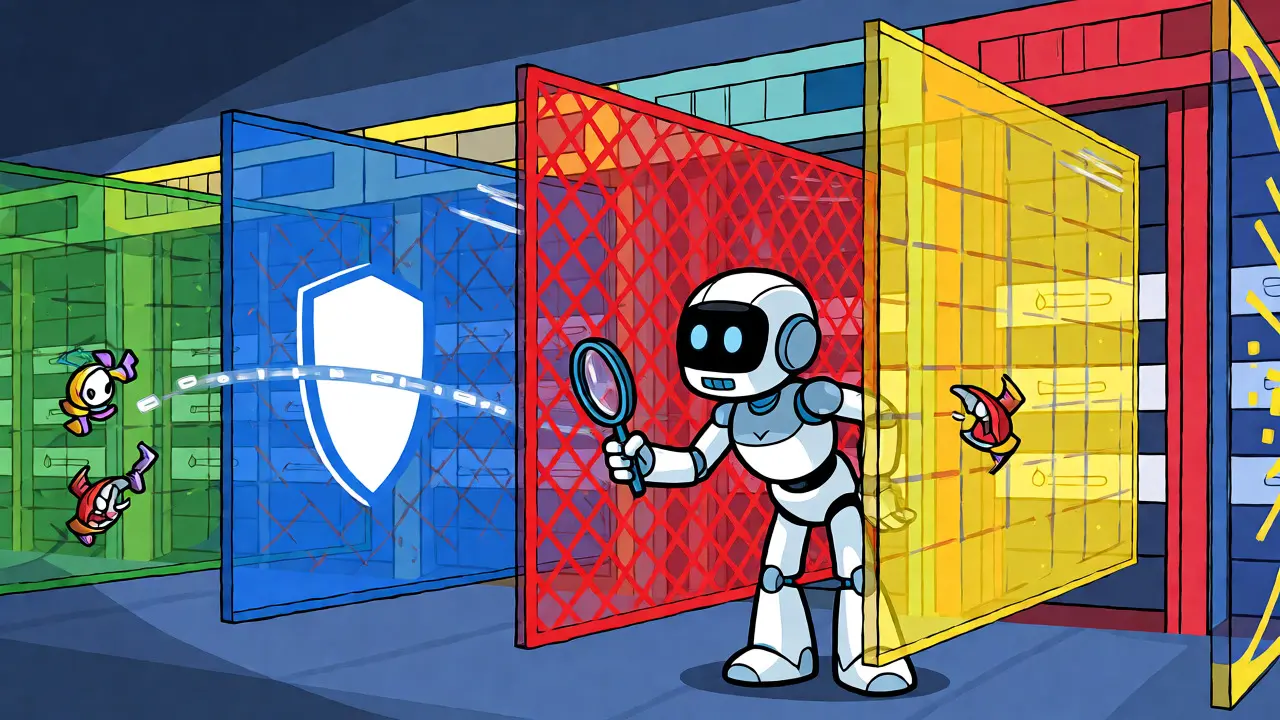
Beyond these foundational techniques, runtime controls are critical. Dynamic filtering should be applied at the prompt, model, and output layers. Don’t just filter inputs; scan outputs for leaked secrets or unexpected formats before they reach the user. Access controls must also evolve. It’s no longer enough to restrict who can access the application; you must enforce permissions at the tool-use level. If an LLM agent tries to call a payment API without explicit authorization, the system should block it regardless of the model’s confidence score.
Designing Robust Escalation Paths
When things go wrong-and they will-you need a plan that doesn’t rely on panic. Escalation paths define exactly how the system responds to anomalies. This is where many organizations fail: they have alerts but no automated actions.
Start with Kill-Switches. These are automated triggers that halt an agent’s execution when specific conditions are met. For example, if an agent attempts to write to a protected directory or exceeds a token budget by 50%, the kill-switch pauses execution and flags the event for review. This prevents runaway costs and destructive actions.
Next, implement Human-in-the-Loop (HITL) gates for high-stakes decisions. Not every output needs human review, but actions with irreversible consequences do. Define clear thresholds: if an LLM generates a legal contract clause, it goes to a lawyer. If it summarizes an email, it auto-sends. The escalation path should specify who gets notified, what information they receive (context, confidence scores, alternative options), and the timeline for response.
Finally, establish Contingency Plans. What happens if your primary LLM provider suffers an outage or releases a version update that breaks your prompts? You need fallback models-perhaps a smaller, local open-source model-that can handle degraded service. Version pinning is essential here; never let vendor updates automatically change your production behavior without testing.
Governance Frameworks and Continuous Monitoring
Governance isn’t a document; it’s a pipeline. Modern LLM governance integrates directly into the DevOps lifecycle. You need continuous monitoring that tracks drift, performance, and compliance in real-time. Static dashboards are insufficient. You need immutable audit trails that record every prompt, response, and tool call. This transparency is vital for debugging and for regulatory compliance under frameworks like the EU AI Act or NIST AI RMF.
Context-aware validation is another key component. Instead of generic unit tests, use adversarial prompts and simulated scenarios during CI/CD pipelines. Test how your model behaves when given ambiguous instructions, conflicting data, or malicious inputs. This proactive testing catches issues before they hit production.
Integrate your AI oversight with existing GRC (Governance, Risk, and Compliance) tools. Map LLM risks to established standards like ISO 27001 or SOC 2. Automation can help here: use LLMs themselves to summarize control evidence and flag non-compliance areas. This creates a feedback loop where governance informs development, and development insights refine governance policies.
Vendor Risk and Dependency Management
If you are using third-party APIs (like OpenAI, Anthropic, or Google), you inherit their risks. Vendor lock-in is a significant strategic concern. Changes in pricing, rate limits, or model deprecations can disrupt your business overnight. To mitigate this, maintain abstraction layers that allow you to swap providers with minimal code changes.
Also, scrutinize vendor terms regarding data usage. Ensure your prompts and responses are not used to train public models unless explicitly agreed upon. Contractual guarantees about uptime and support response times are crucial for high-availability applications. Regularly review vendor security certifications and incident reports. Treat your LLM provider like any other critical infrastructure vendor-with due diligence and contingency planning.
Implementation Checklist for Leaders
Ready to upgrade your AI governance? Start with these concrete steps:
- Inventory Your Assets: Identify every LLM instance, including shadow IT tools employees are using.
- Classify Data Flows: Determine what sensitive data enters and exits each LLM interaction.
- Define Risk Tiers: Assign each use case a risk level based on damage potential and user impact.
- Implement Runtime Guards: Deploy input/output filters and tool-permission checks.
- Set Up Observability: Ensure every transaction is logged with trace IDs for auditing.
- Test Escalation Paths: Run fire drills to see if humans respond correctly to automated alerts.
This structured approach moves you from reactive firefighting to proactive resilience. By embedding controls into the architecture and defining clear human intervention points, you unlock the value of LLMs without exposing your organization to unmanaged chaos.
What is the biggest difference between traditional ML risk management and LLM risk management?
The main difference is determinism. Traditional ML models generally produce consistent outputs for the same input, allowing for static validation. LLMs are stochastic and generate variable outputs, requiring continuous, dynamic monitoring and behavioral testing rather than one-time validation.
How do I handle PII in LLM prompts?
Use a combination of data minimization and differential privacy. Before sending data to an LLM, mask or tokenize personally identifiable information (PII). Implement output filters to catch any residual PII leaks. Consider using private endpoints or self-hosted models for highly sensitive data to avoid third-party exposure.
What is a 'kill-switch' in the context of AI agents?
A kill-switch is an automated mechanism that immediately halts an AI agent's operations when predefined unsafe conditions occur, such as attempting unauthorized actions, exceeding resource limits, or generating outputs that violate safety policies.
Do I need human-in-the-loop for every LLM interaction?
No, that would be too slow and expensive. Reserve human-in-the-loop approval for high-stakes, irreversible, or legally sensitive actions. For routine tasks like summarization or drafting, rely on automated controls and post-hoc sampling audits.
How does vendor lock-in affect LLM risk management?
Vendor lock-in increases operational risk because you depend on a single provider's stability, pricing, and policy changes. Mitigate this by using abstraction layers that allow switching providers, maintaining fallback models, and negotiating contractual terms that guarantee data ownership and service levels.