You’ve probably hit that wall where a Large Language Model (LLM) gives you a confident but completely wrong answer to a tricky question. It sounds smart, it flows well, but the logic is broken. This isn’t usually because the model is "dumb"; it’s because the question requires multiple steps of reasoning, and the model tried to jump straight to the finish line without checking its footing. That’s where Self-Ask and decomposition prompting come in. These aren’t just buzzwords from academic papers; they are practical tools that force an AI to break down big problems into small, solvable pieces before giving you an answer.
If you’re building applications with GPT-4o, Claude 3, or Llama 3, you’ve likely noticed that standard prompts struggle with multi-hop questions-queries that require synthesizing information from different sources or steps. For instance, asking "Who won the Master's Tournament the year Justin Bieber was born?" seems simple to a human, but it requires three distinct logical leaps: finding Bieber’s birth year, identifying the tournament winner for that specific year, and confirming the name. Without help, models often hallucinate here. With decomposition, accuracy can jump from around 42% to nearly 79%. Let’s look at how you can actually implement this to stop your AI from guessing.
What Is Self-Ask Prompting?
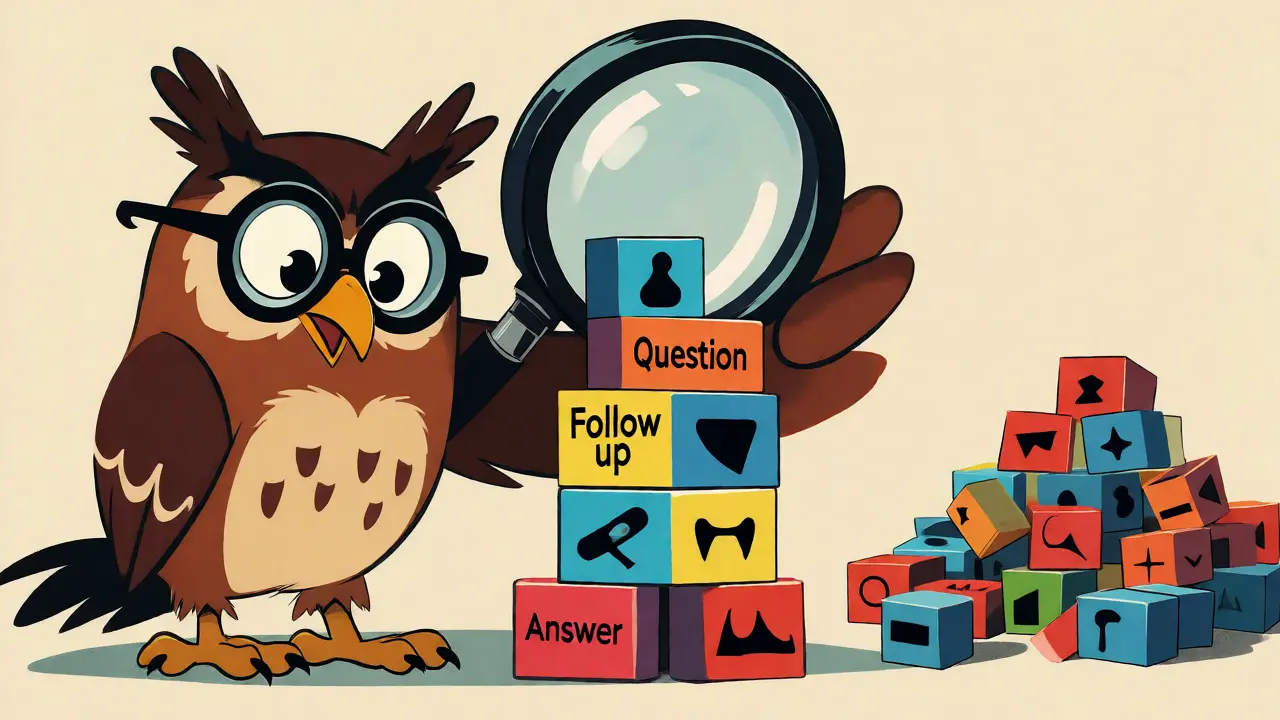
Self-Ask prompting is a technique where the model explicitly generates follow-up questions before answering the main query. Think of it as teaching the AI to interview itself. Instead of saying "Answer this," you instruct the model to say, "To answer this, I first need to know X. What is X? Then, I need to know Y..." This structured approach creates a visible trail of reasoning, which makes errors easier to spot and fix.
The core mechanism relies on specific scaffolding markers. You don’t just ask the question; you provide a template that forces the structure. A typical Self-Ask prompt looks like this:
- Question: The main complex question.
- Follow up: The sub-question the model needs to answer first.
- Intermediate answer: The model’s response to the sub-question.
- Final answer: The conclusion based on the intermediate answers.
This method differs significantly from Chain-of-Thought (CoT). While CoT encourages internal step-by-step reasoning, Self-Ask externalizes those steps as discrete Q&A pairs. This distinction matters because it allows you, the developer, to verify each intermediate step. If the model gets the first sub-question wrong, you can catch it before it cascades into a wrong final answer. Research from RelevanceAI shows that using consistent scaffolding reduces hallucinations in technical documentation generation, though it does increase token usage by about 35-40%.
Decomposition Prompting: Breaking It Down Further
Decomposition prompting, often referred to as DECOMP, takes the concept further by systematically splitting complex problems into simpler sub-tasks. Inspired by human problem-solving strategies, this technique doesn’t just ask follow-up questions; it structures the entire workflow into sequential or concatenated processing phases. According to recent studies, including work published in May 2025, decomposition can improve accuracy on multi-hop scientific reasoning tasks by over 13 percentage points compared to standard Chain-of-Thought methods.
There are two main ways to implement decomposition:
- Sequential Processing: The model solves one sub-problem at a time. It waits for the answer to the first part before moving to the second. This is slower but more accurate for complex mathematical or logical chains.
- Concatenated Processing: All sub-problems are sent to the model simultaneously. This is faster but risks losing context between steps if the dependencies aren’t clear.
Empirical testing suggests that sequential processing yields about 12.7% higher accuracy on complex math problems. Why? Because it prevents the model from trying to hold too many variables in its "working memory" at once. By isolating each step, you reduce cognitive load on the model, leading to cleaner outputs. However, be aware that this increases latency. If you’re building a real-time chatbot, you might need to balance accuracy against speed.
Comparing Techniques: When to Use What
Not every problem needs heavy-duty decomposition. Sometimes, a simple Chain-of-Thought prompt is enough. Here’s how these techniques stack up against each other in terms of performance and cost.
| Technique | Best For | Accuracy Gain (vs. Direct) | Token Cost Increase | Complexity |
|---|---|---|---|---|
| Direct Answer | Simple factual queries | Baseline | Low | Low |
| Chain-of-Thought (CoT) | Logical puzzles, basic math | +5-8% | Moderate | Medium |
| Self-Ask | Multi-hop factual synthesis | +10-15% | High (+35%) | Medium-High |
| Decomposition (DECOMP) | Scientific reasoning, code gen | +13-18% | Very High (+47%) | High |
Notice the trade-off. As you move from Direct Answer to Decomposition, accuracy goes up, but so do costs and complexity. For frontier models like Claude 3.5 Sonnet, the gains from Self-Ask diminish slightly because these models already have robust internal reasoning capabilities. However, for smaller models like Llama 3 8B, decomposition provides a massive boost-up to 14.7% improvement in some benchmarks. So, if you’re running local models or cheaper APIs, these techniques are essential. If you’re paying premium rates for GPT-4o, you might get away with lighter prompting for simpler tasks.
Step-by-Step Implementation Guide
Ready to try this out? Don’t just throw a complex question at the API. Follow this three-phase approach to avoid common pitfalls.
Phase 1: Identify Natural Decomposition Points
Before writing code, solve the problem yourself. Break it down on paper. If you can’t explain the steps clearly, the model won’t either. Look for dependencies: Does Step B require the result of Step A? If yes, you need sequential processing. If the steps are independent, you might use concatenated processing. A common mistake is creating redundant sub-questions. About 34.7% of initial attempts fail because users ask the same thing twice in different words.
Phase 2: Build the Scaffolding
Create a prompt template that enforces the structure. Here’s a basic example for a Self-Ask prompt:
Question: [User Question]
Follow up: [Model generates first sub-question]
Intermediate answer: [Model answers sub-question]
Follow up: [Model generates second sub-question]
Intermediate answer: [Model answers sub-question]
Final answer: [Model synthesizes all answers]
Crucially, add a verification step. After each intermediate answer, include a check: "Does this answer make sense in context? Yes/No." If the model says "No," prompt it to revise. This simple addition catches errors early and improves reliability significantly.
Phase 3: Iterate and Refine
Your first version won’t be perfect. Test it on edge cases. Does it handle abstract philosophical questions well? Often, decomposition fails on creative or subjective tasks because it forces artificial dichotomies where none exist. In one case study, users reported complete breakdowns on abstract questions because the rigid structure created false constraints. If your task is creative, stick to Chain-of-Thought. If it’s factual or analytical, go full decomposition.
Common Pitfalls and How to Avoid Them
Even with good intentions, implementation can go wrong. Here are the top issues developers face, according to community feedback and technical analysis:
- Inconsistent Depth: Sometimes the model asks five sub-questions, sometimes only one. Fix this by specifying the number of steps in your prompt: "Break this down into exactly three sub-questions."
- Cascading Errors: If Step 1 is wrong, Step 2 will be wrong, and the final answer will be confidently incorrect. Mitigate this by adding external verification or cross-checking intermediate answers against known facts if possible.
- Latency Issues: More tokens mean slower responses. For user-facing apps, consider streaming the intermediate answers so the user sees progress rather than waiting for the final result.
- Over-Decomposition: Don’t break down simple questions. Asking "What is 2+2?" with Self-Ask is overkill. Reserve these techniques for genuinely complex, multi-hop queries.
Also, watch out for "reasoning path fragility." A minor error in an early step can cascade into a major failure later. McKinsey’s AI Practice found that this affects nearly 30% of complex implementations. Regular auditing of your logs helps identify where the chain breaks.
Real-World Applications and Future Trends
These techniques aren’t just theoretical. They’re being used heavily in legal tech for contract analysis, medical diagnostics support, and financial analytics. In fact, enterprise adoption of decomposition techniques grew from 12.3% in early 2024 to nearly 39% by late 2025. Companies are realizing that auditability is key for compliance, especially in regulated industries. The EU AI Office now recommends auditable decomposition chains for high-risk AI applications, making these techniques not just useful, but potentially necessary for certain deployments.
Looking ahead, automation is taking over. Newer models like GPT-4.5 are starting to generate optimal sub-questions automatically, reducing the need for manual scaffolding. Anthropic has also announced plans for automatic fact-checking at each decomposition step in future Claude versions. But even as models get smarter, understanding the principles of decomposition remains valuable. It helps you debug when things go wrong and design better workflows for complex tasks.
So, next time your LLM gives you a weird answer, don’t just tweak the temperature. Try breaking the question down. Force the model to show its work. You’ll likely find that the path to a correct answer is paved with good sub-questions.
What is the difference between Self-Ask and Chain-of-Thought?
Chain-of-Thought (CoT) encourages the model to reason internally in a step-by-step manner, often producing a narrative explanation. Self-Ask, however, explicitly structures the reasoning as a series of generated sub-questions and their corresponding answers. This makes the reasoning process more modular and easier to audit, as each step is isolated and verifiable.
Does decomposition prompting increase API costs?
Yes, typically by 35-47%. Because the model must generate additional text for sub-questions and intermediate answers, the total token count increases. This directly impacts API pricing. Developers need to weigh the accuracy benefits against the increased operational costs, especially for high-volume applications.
When should I avoid using decomposition techniques?
Avoid decomposition for creative writing, abstract philosophical questions, or simple factual queries. Decomposition works best on logical, multi-hop, or analytical tasks. On creative tasks, forcing rigid sub-questions can stifle the model's ability to generate nuanced or original content, leading to robotic or overly constrained outputs.
How do I handle errors in intermediate answers?
Implement a verification step after each sub-answer. Ask the model to critique its own intermediate answer (e.g., "Is this correct? Yes/No"). If it says no, prompt it to revise. Additionally, logging these intermediate steps allows for offline debugging and potential correction before the final answer is synthesized.
Do larger models still need Self-Ask prompting?
While frontier models like GPT-4o and Claude 3.5 have improved inherent reasoning, they still benefit from Self-Ask for complex multi-hop tasks. However, the relative gain is smaller compared to smaller models. For very large models, the primary benefit shifts from raw accuracy to transparency and auditability, which are crucial for enterprise applications.