You built a Retrieval-Augmented Generation (RAG) system. You indexed your data, set up vector search, and connected it to an LLM. But when you ask a specific question, the model gives you a hallucinated answer or misses the mark entirely. Why? Because vector similarity is often just topical matching, not true relevance. It finds documents that share keywords or general themes, but it struggles with nuance. This is where document re-ranking saves the day.
Re-ranking isn't magic; it's a second-stage filter. Think of it like hiring. Your initial vector search is the resume screen-it grabs everyone who has the right degree and job title. Fast, but noisy. The re-ranker is the interviewer. It reads the resume and the job description together, spots the subtle fits, and rejects the ones that look good on paper but fail in practice. By adding this step, you drastically improve the quality of context fed into your Large Language Model (LLM).
The Core Problem: Topical Similarity vs. Situational Relevance
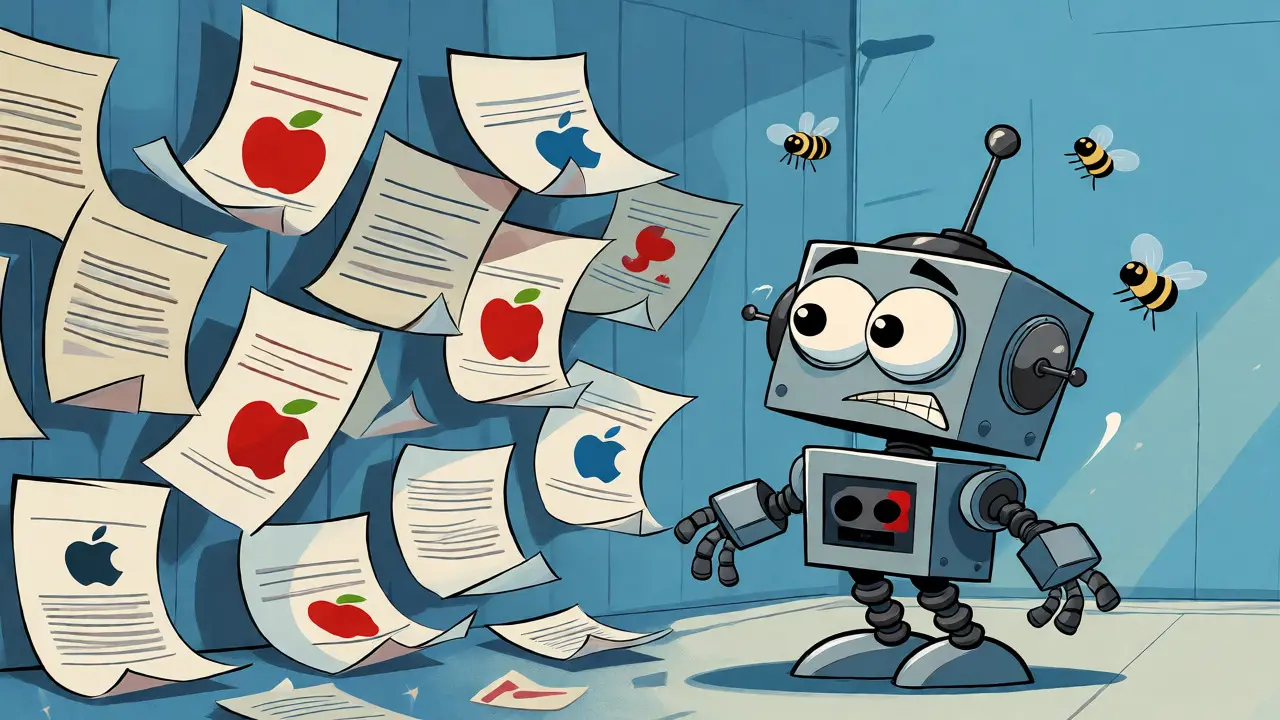
Standard vector databases use embeddings to compress text into numbers. When you query them, they find other vectors that are close in mathematical space. This works great for broad topics. If you search for "apple," you get results about fruit and tech companies. But if you search for "how to fix the apple logo on iOS 17," simple vector search might return generic Apple history pages because they contain the word "Apple" and "iOS." They miss the specific intent: fixing a logo.
This gap between what looks similar and what is actually useful is the primary failure point in many RAG applications. As your document corpus grows denser and more specialized, this problem worsens. A document might contain the exact answer buried in paragraph ten, surrounded by irrelevant technical jargon that skews its embedding. Initial retrieval ranks it low. The LLM never sees it. The user gets a wrong answer.
How Two-Stage Retrieval Works
To fix this, engineers implement a two-stage pipeline. It’s a trade-off between speed and precision.
- Stage 1: Broad Recall (Vector Search)
The system uses fast methods like Approximate Nearest Neighbor (ANN) search or BM25 keyword matching. The goal here is recall-finding every possible document that might be relevant. We typically pull back a larger set, say 50 to 100 candidate chunks. This stage is cheap and fast, ensuring we don't miss the needle in the haystack. - Stage 2: Precise Ranking (Re-Ranking)
We take those 50-100 candidates and feed them into a heavier, smarter model called a re-ranker. This model analyzes each query-document pair individually. It outputs a new relevance score. We then sort these scores and pick the top 5 or 10 most relevant chunks to send to the LLM.
This approach optimizes the balance between retrieval recall (getting all relevant docs) and LLM recall (keeping the context window clean). If you send 100 chunks to the LLM, it gets confused by noise. If you only retrieve the top 5 via vector search, you likely missed the best one. Re-ranking lets you cast a wide net first, then tighten the mesh.
Cross-Encoders: The Engine Behind Precision
Most modern re-rankers are Cross-Encoder Transformer Models. Unlike bi-encoders used in vector search (which process queries and documents separately), cross-encoders process the query and document together as a single input sequence.
This architectural difference is crucial. In a bi-encoder, the semantic relationship is compressed into fixed-length vectors before comparison. Information loss happens. In a cross-encoder, the model attends to interactions between every token in the query and every token in the document. It can spot negations, complex dependencies, and specific entity matches that vector distance misses.
For example, consider a query: "Does the policy exclude remote workers?" A vector search might rank a document titled "Remote Work Benefits" highly because of the word overlap. A cross-encoder reads the sentence "The policy explicitly excludes remote workers from this benefit" and correctly identifies it as highly relevant, even if the overall topic similarity was lower.
| Feature | Bi-Encoder (Vector Search) | Cross-Encoder (Re-Ranking) |
|---|---|---|
| Processing Method | Separate encoding of query and doc | Joint encoding of query-doc pair |
| Speed | Extremely Fast (milliseconds) | Slow (seconds per batch) |
| Accuracy | Moderate (Topical Match) | High (Semantic/Situational Match) |
| Use Case | Initial Candidate Retrieval | Final Relevance Scoring |
| Scalability | Millions of documents | Tens to Hundreds of candidates |
Emerging Techniques: Agentic and Multimodal Re-Ranking
The field isn't static. New methods are pushing boundaries beyond standard cross-encoders. One notable development is JudgeRank, an agentic approach that mimics human reasoning. Instead of just outputting a score, it breaks down the task: analyzing the query, summarizing the document in relation to the query, and then judging relevance. This multi-step reasoning allows it to handle complex, zero-shot tasks better than traditional fine-tuned models, performing on par with state-of-the-art rerankers on benchmarks like BEIR.
Multimodal RAG presents another challenge. How do you re-rank images alongside text? Standard CLIP-based embeddings often struggle with nuanced multimodal relevance. Recent research focuses on adaptive relevancy scores that dynamically select the number of entries based on confidence, rather than a fixed top-k. This flexibility helps when dealing with diverse data types where a fixed threshold fails.
Implementation Strategy: Balancing Cost and Quality
Adding a re-ranker adds latency. You must measure this impact. If your application requires sub-second responses, a heavy cross-encoder might be too slow. Here is how to tune it:
- Optimize Candidate Size: Don't re-rank 1,000 documents. Start with 20-50. Test if increasing this number improves final answer accuracy. Diminishing returns hit quickly.
- Choose the Right Model: General-purpose models like Cohere Rerank or BAAI/bge-reranker work well for broad domains. For specialized fields like legal or medical, fine-tuning a smaller cross-encoder on domain-specific pairs yields better results than using a massive general model.
- Batch Processing: If you have multiple queries, batch the re-ranking calls. Modern GPUs handle parallel inference efficiently, reducing the per-query cost.
Remember, the goal isn't perfect ranking; it's sufficient ranking. You need the correct chunk in the top 3 positions so the LLM can use it. You don't need to perfectly order chunks 4 through 10.
Why Factuality Depends on Relevance
You mentioned factuality control. This is directly tied to re-ranking. LLMs are probabilistic engines. If you feed them irrelevant context, they try to force an answer from it, leading to hallucinations. If you feed them precise, high-relevance context, they ground their generation in facts.
Re-ranking acts as a gatekeeper for truth. By filtering out documents that are topically related but factually unhelpful, you reduce the "noise-to-signal" ratio. This makes the LLM's job easier. It spends fewer parameters trying to ignore bad info and more trying to synthesize good info. In enterprise settings, this distinction determines whether your chatbot is trusted or ignored.
Is re-ranking always necessary for RAG?
Not always. If your dataset is small, homogeneous, and your queries are simple keyword matches, vector search alone might suffice. However, for complex, ambiguous, or domain-specific queries, re-ranking significantly boosts performance. If you notice your LLM answers are vague or incorrect despite having the right data in the index, re-ranking is likely needed.
What is the typical latency increase from adding a re-ranker?
It depends on the model size and hardware. A lightweight cross-encoder might add 50-100ms per query. A larger LLM-based re-ranker could add several seconds. Most production systems aim to keep total latency under 2-3 seconds, so re-ranking is usually applied to a small candidate set (e.g., top 20) to stay within budget.
Can I use an LLM itself as a re-ranker?
Yes, this is known as LLM-as-a-Judge. You prompt a powerful LLM to rate the relevance of each document. It offers high accuracy and reasoning capabilities but is computationally expensive and slower than dedicated cross-encoder models. It's often used for offline evaluation or high-stakes, low-volume queries.
How does re-ranking affect token costs?
Ironically, it can save money. By filtering out irrelevant chunks, you send less total text to the final generative LLM. Since you pay per token for generation, sending 5 highly relevant chunks instead of 20 mixed-quality chunks reduces input token counts for the generator, potentially lowering overall API costs despite the extra compute for re-ranking.
Which re-ranking models are popular in 2026?
Popular choices include Cohere Rerank for ease of use, BAAI/bge-reranker for open-source flexibility, and NVIDIA NeMo Retriever components for enterprise integration. Specialized models fine-tuned on specific domains (like finance or healthcare) often outperform generalists in niche applications.