You see the headlines: "AI Solves Olympiad Math." You read the blog posts claiming your favorite large language model (LLM) is now a certified mathematician. But if you've ever tried to use one of these models for actual research-level math or complex financial modeling, you know the reality is messier. The gap between scoring high on a benchmark and genuinely understanding mathematics is wider than most marketing materials admit.
As we stand in late 2026, the field of mathematical reasoning benchmarks has become the critical battleground for evaluating next-generation LLMs. These aren't just tests of arithmetic; they are rigorous probes designed to determine if a model can reason, prove, and adapt-or if it’s just memorizing patterns from its training data. If you’re an engineer, researcher, or tech leader trying to decide which model to trust with your critical calculations, you need to look past the raw accuracy percentages. Here is what the current landscape actually tells us about where AI stands in mathematics.
The Evolution of Testing: From Arithmetic to Proofs
A few years ago, if a model could solve grade-school word problems, we were impressed. Today, that bar has shifted dramatically. The foundational MATH dataset, created by Hendrycks et al. in 2021, established the initial gold standard with 12,500 curated competition-level problems. For a long time, topping this leaderboard meant you had a powerful model. But as models got smarter, the test got easier relative to their capability, leading to concerns about data contamination-basically, models might have seen the answers during training.
To combat this, the community developed harder, more nuanced benchmarks. We now have a tiered system:
- GSM8k & GSM-Symbolic: While GSM8k covers grade-school multi-step reasoning, its successor, GSM-Symbolic, uses symbolic templates to generate diverse variations of the same problem. This prevents memorization and tests true logical robustness.
- OlympiadBench: This targets undergraduate competition levels, pushing models into territory that requires creative problem-solving rather than rote application of formulas.
- PhD-Level Proof Benchmarks: The newest frontier. A recent report from Berkeley EECS introduced a benchmark based on Roman Vershynin’s 'High-Dimensional Probability,' featuring 77 proof-based questions. These aren't multiple-choice; they require constructing novel proofs.
The progression isn't just about difficulty; it's about fidelity. Early benchmarks measured final answer accuracy. Modern benchmarks like the USAMO 2025 evaluation measure the quality of the entire solution path, judged by human experts or sophisticated automated frameworks.
Where Top Models Actually Stand
Let’s look at the numbers. It’s tempting to think that because a model scored 90% on a standard test, it’s nearly perfect. The reality is more fragmented. Leading closed-source models like Gemini 2.5 Pro and Claude 3.7 dominate standard benchmarks. As of early 2025, Gemini 2.5 Pro hit 89.1% on GSM8k and 68.1% on the MATH dataset. Claude 3.7 wasn’t far behind.
But here is the catch: performance collapses under stress. When researchers applied perturbation testing-changing variable names, adding irrelevant clauses, or altering numerical values slightly-accuracy dropped by 15 to 30 percentage points across all major models. This exposes a fundamental weakness: many models rely on pattern recognition tied to specific phrasings rather than abstract mathematical understanding.
| Model Type | Standard GSM8k Accuracy | MATH Dataset Accuracy | Perturbed (GSM-Symbolic) Drop | USAMO Full-Solution Score |
|---|---|---|---|---|
| Gemini 2.5 Pro | 89.1% | 68.1% | -22% | 25% |
| Claude 3.7 | 87.3% | 65.4% | -25% | <5% |
| ChatGPT o3 | ~88% | ~67% | -20% | N/A (Chain-of-Thought focus) |
| Open-Source (DeepSeek/Qwen) | 84-86% | 60-63% | -28% | <5% |
The disparity is starkest in rigorous proof generation. On the USAMO 2025 evaluation, even top-tier models struggled. Human annotators found that while models often got the final number right, their intermediate steps frequently contained circular reasoning (32% of cases), incorrect assumptions (27%), or incomplete logic (24%). This means you cannot blindly trust an LLM to generate a publishable mathematical proof without heavy human oversight.
The Memorization vs. Reasoning Dilemma
Why does this happen? It comes down to how these models learn. They are statistical engines predicting the next token. In standard benchmarks, there is a strong correlation between common problem structures and known solutions. The model learns: "If I see X, output Y." It doesn't necessarily understand *why* Y follows X.
Dr. Soumith Chintala, co-creator of PyTorch, pointed out that current benchmarks are often "gamed" through pattern recognition. His team showed that simply changing the numbers in a GSM8k problem caused significant error rates, proving the model wasn't adapting its logic but recalling a template. Apple Machine Learning Research confirmed this, noting that performance declines by approximately 2.3% for every additional clause added to a problem statement. This fragility is a major red flag for real-world applications where problems are rarely perfectly clean.
Furthermore, the ability to handle novel problem structures remains limited. Models excel when the problem resembles something in their training distribution. When faced with a truly new type of constraint or a unique combination of concepts, they hallucinate confidently. They don't say "I don't know"; they invent a plausible-sounding but incorrect derivation.
Hybrid Architectures: The Real Solution?
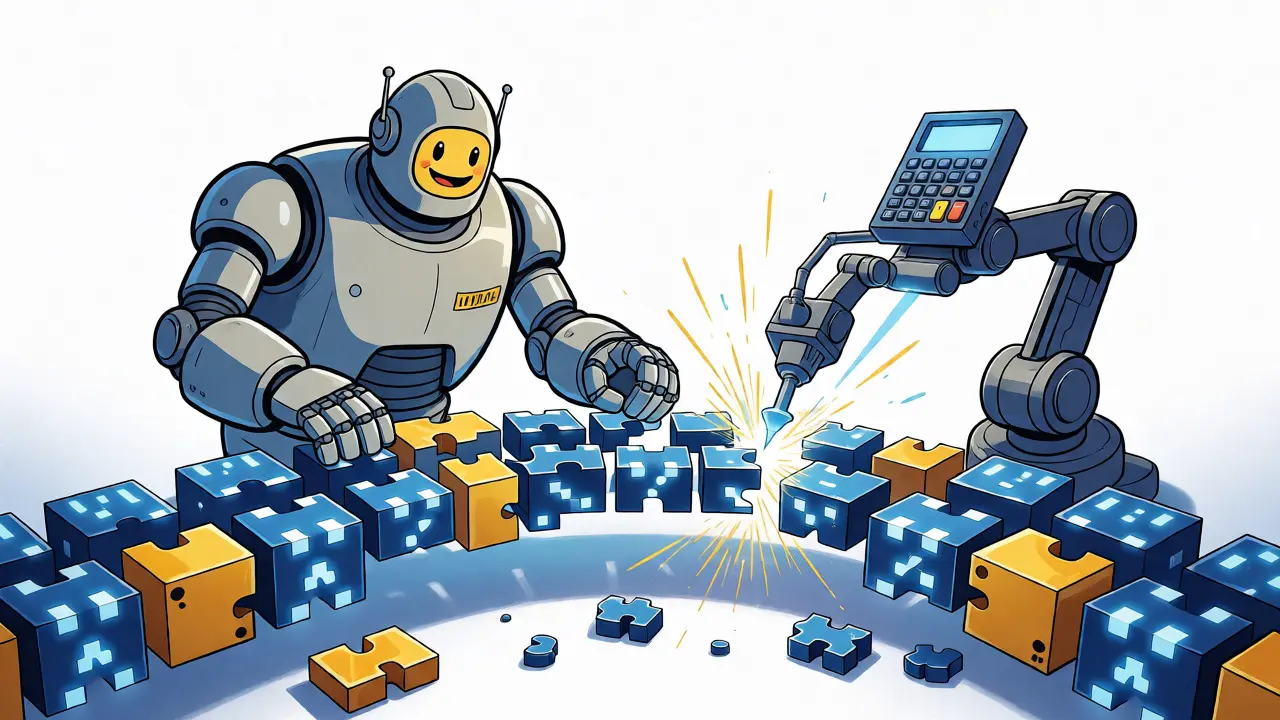
If pure LLMs struggle with rigor, what works? The industry is shifting toward hybrid systems. Instead of relying solely on neural networks, engineers are integrating symbolic engines like SymPy, Wolfram Alpha, or formal theorem provers.
Consider Google DeepMind’s AlphaGeometry 2.0. Released in May 2025, it combines neural language models with formal geometric solvers. On IMO geometry problems, it achieved 74% accuracy compared to 58% for pure LLM approaches. Why? Because the neural network handles the intuitive part-identifying which geometric principles apply-and the symbolic engine handles the rigorous execution.
This trend extends to general math tasks too. Developers report that integrating a symbolic execution layer adds about 150ms of latency per query but boosts accuracy on complex problems by 22-38 percentage points. The optimal architecture isn't just a bigger brain; it's a brain connected to a calculator that understands algebra. OpenAI’s ChatGPT o3 exemplifies this shift with extended chain-of-thought reasoning, allowing the model to "think" for longer sequences, backtrack, and verify steps internally before committing to an answer.
Practical Implications for Developers and Researchers
So, how should you use these tools today? Don't treat them as black boxes. If you are building an app for K-12 tutoring, current models are fantastic-they achieve 92% accuracy on standard problems and significantly reduce teacher workload. However, for research-level math or quantitative finance, caution is required.
Here are three rules of thumb for implementing math-capable LLMs:
- Always Perturb Test: Before deploying, run your specific use case against GSM-Symbolic-style variations. If accuracy drops more than 10%, your model is likely memorizing, not reasoning.
- Use Verification Layers: Never accept a raw LLM output for critical calculations. Pipe the result through a symbolic verifier or a secondary check. Gartner predicts that by 2027, all enterprise-grade math LLMs will incorporate formal verification layers.
- Account for Latency in Hybrid Systems: If you use tool-integrated models (like Gemini calling Python), expect higher latency. Design your UX to handle asynchronous processing for complex queries.
Regulatory pressure is also mounting. The EU AI Act updates from June 2025 require mathematical verification for AI systems in financial modeling and structural engineering. This isn't just best practice; it's becoming law. Pure LLM outputs may not suffice for compliance in these high-stakes domains.
The Future: Beyond Accuracy Metrics
We are moving away from single-number scores. New benchmarks like MathOdyssey evaluate both solution accuracy and reasoning quality across 15,000 problems ranging from K-12 to research level. Early results show even top models scoring below 40% on research-level tasks. This suggests we haven't cracked the code on advanced mathematical cognition yet.
Noam Brown from OpenAI noted that recent progress represents a "quantitative change in thinking time" rather than a qualitative breakthrough in reasoning logic. Models are getting better at simulating thought processes over longer contexts, but the underlying mechanism still lacks the axiomatic consistency of human mathematical thought. Until we integrate formal methods deeply into the training loop, LLMs will remain brilliant assistants but unreliable authors of truth.
Why do LLMs fail at math despite high benchmark scores?
LLMs often rely on pattern recognition and memorization of training data distributions rather than genuine logical deduction. When problems are altered slightly (perturbation testing), models that merely memorized patterns lose accuracy, revealing they lack robust abstract reasoning capabilities.
What is the difference between GSM8k and GSM-Symbolic?
GSM8k contains static grade-school math word problems. GSM-Symbolic uses symbolic templates to generate thousands of variations of those problems with different numbers and phrasings. This helps distinguish between models that understand the underlying logic and those that just memorized specific problem instances.
Can current LLMs generate valid mathematical proofs?
Generally, no. While models can sometimes produce correct final answers, evaluations on rigorous benchmarks like USAMO 2025 show that full-solution reasoning often contains circular logic, incorrect assumptions, or incomplete steps. Expert human review is currently mandatory for any serious proof generation.
How does tool integration improve math performance?
Models like Gemini 2.5 Pro and ChatGPT o3 can invoke external tools like Python, SymPy, or Wolfram Alpha. By offloading calculation-heavy or symbolic manipulation tasks to these deterministic engines, the LLM focuses on problem decomposition and interpretation, significantly reducing arithmetic errors and improving overall accuracy.
Are open-source models competitive with closed-source ones for math?
The gap has narrowed significantly. Specialized open-source models like DeepSeek-Math and Qwen-Math-Instruct achieve within 3-5 percentage points of leaders like Gemini and Claude on standard benchmarks. However, closed-source models still tend to perform better on complex, multi-step reasoning tasks requiring extensive context management.