You built a cool Generative AI chatbot. It answers questions, drafts emails, and maybe even writes code. But if you can’t prove exactly what it said, who asked it, and why it said that, you’re flying blind. In late 2024, IBM lost $47 million in a lawsuit against an AI vendor not because the AI was wrong, but because they couldn’t reconstruct the specific prompts that led to bad outputs. That’s the cost of skipping AI auditing.
Auditing AI isn’t just about checking boxes for regulators anymore. It’s your safety net. With the EU AI Act fully enforcing documentation rules by mid-2026 and California’s SB 1047 tightening requirements, vague records won’t cut it. You need concrete evidence. This guide breaks down exactly what logs you need, how to capture them without slowing down your system, and how to avoid the privacy traps that catch most companies off guard.
Why Traditional Logging Fails with AI
If you treat an LLM like a standard database, you’ll miss critical context. A traditional log entry might say "User X requested data." An AI log needs to say "User X asked 'How do I fire an employee?' at 2 PM, using Model v3.5, which retrieved Document Y, resulting in Output Z with 89% confidence."
The difference matters because AI is probabilistic, not deterministic. The same prompt can yield different results depending on temperature settings, model version updates, or hidden context windows. Without capturing these variables, debugging a hallucination becomes guesswork. According to KPMG’s 2025 research, 78% of organizations struggle specifically with establishing these complete audit trails for generative systems. They try to copy their SQL logging strategies, but those strategies ignore the semantic layer entirely.
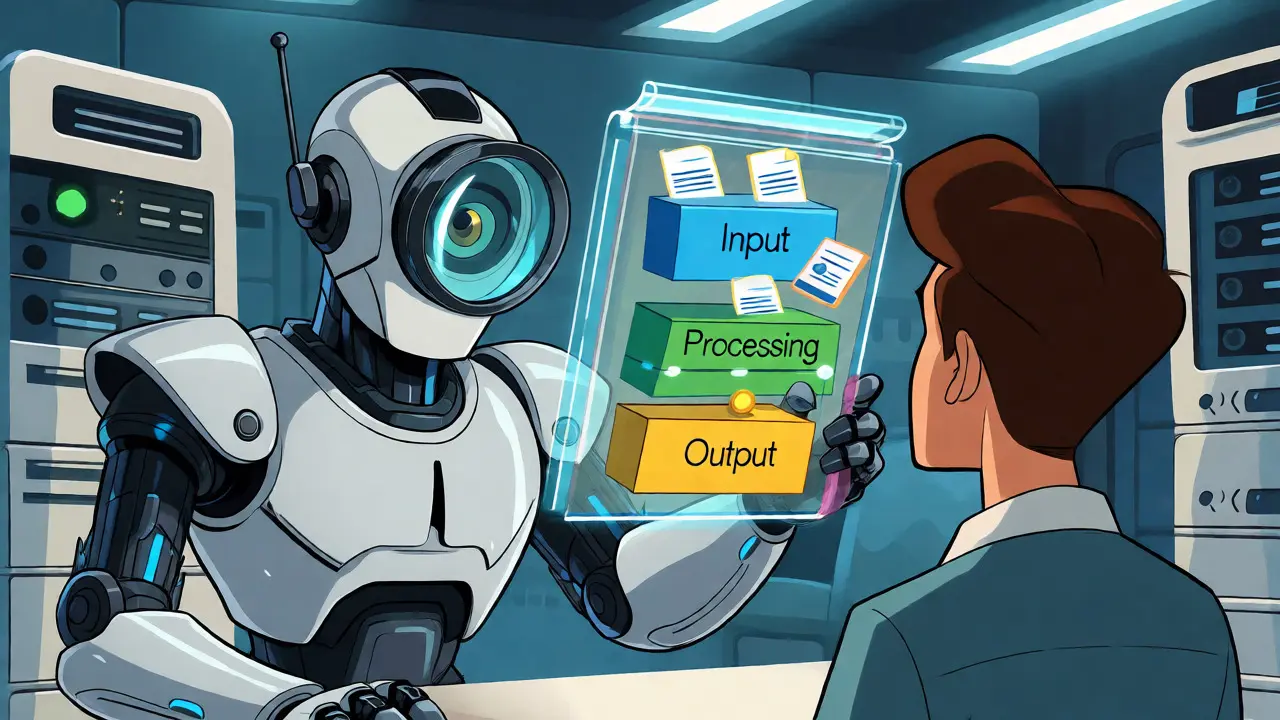
You need to track three distinct layers:
- The Input Layer: The raw user prompt, plus any system instructions (system prompts) injected before the user text.
- The Processing Layer: Metadata about the model itself-version, parameter settings (temperature, top-p), and any external tools or RAG (Retrieval-Augmented Generation) sources accessed.
- The Output Layer: The final response, but also rejected alternatives and confidence scores. Did the model almost choose a different answer? That “near-miss” data is gold for tuning performance.
The Core Requirements: What Must Be Logged?
Let’s get specific. You don’t need to log every single token generated, but you do need a structured record of interactions. ISACA’s 2025 AI Audit Toolkit outlines the minimum viable product for compliant logging. If you’re missing any of these, you’re vulnerable.
| Data Category | Specific Attributes to Capture | Why It Matters |
|---|---|---|
| User Context | User ID, Role/Permission Level, IP Address, Session ID | Establishes accountability. Who triggered the action? Were they authorized? |
| Prompt Details | Raw Text, Timestamp, Language Code, Input Hash (SHA-256) | Proves what was actually asked. Hashing prevents tampering with historical logs. |
| Model State | Model Version, Temperature, Max Tokens, System Prompt Version | Recreates the environment. Helps debug issues when models are updated. |
| Output & Confidence | Final Response, Confidence Score, Latency (ms), Token Count | Measures quality and cost. High latency or low confidence flags potential issues. |
| Source Provenance | RAG Source IDs, Citation Links, External API Calls Made | Verifies facts. Critical for legal defense against misinformation claims. |
Notice the inclusion of "Input Hash." Storing raw prompts is risky due to PII (Personally Identifiable Information). By hashing sensitive fields before storage, you maintain integrity without exposing private data. This technique reduced GDPR fines for several healthcare providers in 2025 by ensuring patient names weren’t sitting in plain-text logs.
Technical Implementation: Balancing Speed and Detail
Here’s the trade-off no one talks about enough: logging slows things down. MIT’s 2025 LLM Observatory found that comprehensive logging adds 8-12 milliseconds of latency per transaction. For a chatbot, that’s barely noticeable. For high-frequency trading algorithms or real-time fraud detection, it’s fatal.
You have two main architectural choices:
Synchronous Logging
The system waits until the log is written before responding to the user. This guarantees zero data loss but hurts performance. Use this only for high-stakes decisions where proof is more important than speed, such as loan approvals or medical triage recommendations.
Asynchronous Logging
The system responds immediately and sends log data to a queue (like Kafka or AWS Kinesis) in the background. This keeps user experience snappy. However, if your server crashes before the queue flushes, you lose those logs. To mitigate this, use write-ahead logging techniques or ensure your message broker has persistent storage enabled.
Most enterprises in 2026 lean toward asynchronous logging with a fallback mechanism. If the async write fails after three retries, the system triggers a synchronous write for that specific transaction to ensure nothing slips through the cracks.
Navigating Privacy and Compliance Traps
Logging everything creates a new problem: you’re now storing massive amounts of potentially sensitive data. Professor David Silverman from Harvard Law School warns that 31% of audited systems inadvertently capture PII in prompt logs that should have been redacted. Imagine logging a doctor’s query: "Patient John Doe, DOB 01/01/1980, symptoms..." If that log leaks, you’ve got a HIPAA violation on your hands.
To stay compliant with GDPR Article 22 and similar regulations, you must implement data minimization protocols. Here’s a practical checklist:
- Pre-processing Redaction: Run a lightweight NER (Named Entity Recognition) model on inputs before logging. Replace names, SSNs, and credit card numbers with placeholders like [NAME] or [SSN].
- Tiered Retention Policies: Don’t keep all logs forever. Financial services often require 7-10 years (per FINRA Notice 25-07). Healthcare might need 6 years (HIPAA). General customer support chats? Maybe 90 days is enough. Set automatic deletion jobs based on data classification.
- Access Controls: Not everyone needs to see raw prompts. Your marketing team doesn’t need access to HR chatbot logs. Restrict log access via role-based permissions.
One major pitfall involves multi-turn conversations. Many systems fail to link follow-up questions to the initial context. If a user asks, "What’s the capital of France?" then says, "And its population?", your log might show two disconnected entries. Modern audit frameworks require session stitching-linking these interactions under a single Session ID so auditors can trace the full conversation flow.
Choosing Your Audit Tool: Buy vs. Build
Should you build a custom logger or buy a platform? The market offers everything from open-source libraries to enterprise suites costing over $100k annually.
Open-Source Solutions (e.g., LangChain Audit Tools): These offer 100% customization and no licensing fees. But they demand significant engineering time. Forrester estimates 38% more implementation time compared to commercial tools. You’ll need Python and SQL skills to parse the logs effectively. Best for startups or teams with strong DevOps capabilities.
Cloud-Native Services (e.g., AWS Audit Manager for AI): Great for scalability, handling billions of transactions daily. They integrate seamlessly with existing cloud infrastructure. However, interpretability scores are lower (68/100), meaning you might get the data but struggle to extract insights without additional BI tools. Best for large enterprises already deep in the AWS/Azure ecosystem.
Specialized Platforms (e.g., AuditAI Pro, Whisperit): These focus purely on governance. They score high on interpretability (92/100) and come with pre-built compliance templates for GDPR and SOC2. The downside? Vendor lock-in and higher costs. Whisperit, for instance, uses SHA-256 cryptographic hashing to prevent tampering, which is crucial for legal admissibility. Best for regulated industries like finance and healthcare where audit trails must stand up in court.
When evaluating vendors, ask this question: "Can your tool export logs in a standardized format like JSON or Protocol Buffers?" Proprietary formats are a nightmare if you switch providers later. Also, check compatibility with your specific LLM provider. Some proprietary models, like Anthropic’s Claude series, expose only 62% of required metadata points, limiting what specialized tools can actually capture.
Real-World Impact: Why It Pays Off
Auditing isn’t just a cost center; it’s a risk mitigator. JPMorgan Chase’s 2025 implementation of prompt-output correlation analysis reduced false positives in fraud detection by 63%. By analyzing *why* the AI flagged a transaction, they refined their models faster than competitors.
Siemens detected a 12.7% performance degradation in their procurement AI before it impacted operations, saving an estimated $3.2 million. How? Their audit logs showed a shift in input patterns that correlated with lower confidence scores. Without those logs, the error would have persisted unnoticed for months.
Conversely, ignoring these practices leads to expensive surprises. A mid-sized healthcare provider faced a $285,000 GDPR fine because their aggressive logging captured patient data in system logs despite having proper input filters elsewhere. The lesson? Logging strategy must be integrated with privacy engineering from day one, not bolted on afterward.
Next Steps for Implementation
Ready to tighten up your AI governance? Start here:
- Map Your Touchpoints: Identify every place users interact with AI. Chatbots, internal search, code assistants. Prioritize high-risk areas first (hiring, lending, health).
- Define Minimum Viable Logs: Don’t try to capture everything at once. Start with User ID, Timestamp, Prompt, Output, and Model Version.
- Implement Redaction: Add a PII scrubber step before writing to your log database.
- Set Retention Rules: Decide how long to keep data based on legal requirements and business value.
- Test Recovery: Simulate a failure. Can you reconstruct a specific interaction from six months ago using only your logs? If not, refine your schema.
Auditing AI usage transforms black-box magic into accountable engineering. It gives you the data to improve models, defend against lawsuits, and satisfy regulators. Start small, automate early, and never let your logs become a graveyard of unread data.
Do I need to log every single character typed by the user?
No, you generally log the final submitted prompt, not keystrokes. However, for debugging UI issues, some systems capture intermediate drafts. Focus on the final input sent to the model, along with any system-level instructions prepended to it.
How long should I retain AI audit logs?
Retention depends on your industry. Financial institutions typically need 7-10 years (FINRA/SEC rules). Healthcare requires at least 6 years (HIPAA). General retail or tech companies often find 90 days to 1 year sufficient for operational improvements, unless litigation holds apply.
What is the biggest privacy risk in AI logging?
Capturing Personally Identifiable Information (PII) in plain text. Users often paste sensitive data into prompts. Always implement automated redaction or hashing of sensitive entities (names, SSNs, addresses) before storing logs to comply with GDPR and CCPA.
Does logging slow down my AI application?
Yes, synchronous logging adds 8-12ms of latency. Most modern implementations use asynchronous logging to minimize impact on user experience, pushing logs to a queue in the background. This ensures responsiveness while maintaining data integrity.
Can I audit open-source models like Llama 3?
Yes, but it’s harder. Open-source models don’t always expose built-in telemetry like proprietary APIs. You may need to instrument the inference engine manually to capture confidence scores and token usage. Only 44% of tested tools handle Hugging Face model interactions correctly, so verify vendor compatibility.
The distinction between deterministic and probabilistic logging is the crux of the matter here. Traditional audit trails assume a linear cause-and-effect relationship, which simply does not exist in Large Language Models. If one fails to capture the temperature settings and top-p sampling parameters alongside the prompt, the log is effectively useless for reproducibility. Furthermore, the suggestion that asynchronous logging with write-ahead techniques is the optimal solution overlooks the potential race conditions in distributed systems during high-load scenarios. One must ensure that the message broker's persistence layer is configured correctly, otherwise, the 'zero data loss' guarantee becomes a fallacy. The IBM example cited is particularly telling; it wasn't the AI's output that was wrong, but the inability to correlate the input state with the output result due to poor metadata retention.
They don't want you to know this but the cloud providers are already selling your prompts to third parties. That $47 million loss? It’s nothing compared to what they’ll charge us when they realize we’re all just training their models for free. Keep your logs local or keep your mouth shut. 😡
This is such a vital topic! 🌟 I think the part about session stitching is often overlooked by teams who are focused on single-turn interactions. When users engage in multi-turn conversations, the context window shifts dynamically, and if we don't link those turns, we lose the narrative arc of the user's intent. It’s like trying to understand a movie by watching random clips without knowing the plot order. 🎬 We need to approach this with an inclusive mindset, ensuring that our logging frameworks don't inadvertently bias against certain types of user interactions or dialects. Let’s build systems that respect the human element behind every query. 🤝✨
The sheer volume of unstructured text generated by these systems creates a veritable tsunami of data that most legacy infrastructure cannot handle without drowning. It is akin to attempting to drink from a fire hose while simultaneously trying to identify specific droplets of poison within the flow. The privacy implications are equally harrowing, as the redaction algorithms frequently fail to catch contextual PII, leaving organizations exposed to regulatory lightning strikes. One must consider the ethical weight of storing these digital breadcrumbs, for they reveal not just what was asked, but the very psyche of the interrogator. It is a delicate dance between transparency and obscurity, where one misstep can lead to catastrophic reputational damage. 🌊📜⚖️
While the technical details are adequately covered, the analysis lacks depth regarding the cost-benefit ratio of implementing specialized platforms versus open-source solutions. Forrester’s estimate of 38% more implementation time is a broad generalization that ignores the variability in team expertise. Moreover, the claim that proprietary formats are a nightmare assumes a lack of standardization efforts, which is arguably short-sighted given the current push towards JSON-LD and other semantic web standards. The article presents a somewhat idealized view of asynchronous logging, failing to address the operational overhead of maintaining message queues at scale. A more critical examination would have considered the diminishing returns of capturing near-miss data for models that are rarely retrained. Overall, the piece reads like marketing collateral rather than a rigorous audit guide.
Sure, let's ignore the fact that half the people writing these prompts don't even know what 'temperature' means. Great advice for the tech bros, terrible for the rest of us. 🙄
I see so many people missing the point here. You're all focusing on the tools, but the real issue is the governance structure. If your C-suite doesn't understand why they need to pay for audit logs, you're doomed before you start. I've seen projects fail because legal wanted everything and engineering wanted nothing. It’s a mess. 💅
Great insights everyone! @Ian Mason-Laurence, you made a really strong point about the race conditions in async logging-that’s definitely something to watch out for in high-traffic environments. And @Ejike Ugwu, while the paranoia might be a bit high, the concern about data ownership is totally valid and worth keeping in mind. It’s helpful to hear different perspectives on how to balance speed with security. Let’s keep supporting each other as we figure out these new AI governance challenges together! 💪😊